The Launch Call
Shipping under incomplete data: designing tests that can fail, pre-committing to kill conditions, and telling a sample that can answer the question from one that can't.
Chapter 5 · 4 ideas · 11 checks · 17 min
Start here
The beta has been running six weeks. Launch is in six days. Marketing has been briefed, the blog post is drafted, and two people have rearranged their holidays around the date.
The dashboard says: 40 users enrolled, 62% completed the new flow, feedback mixed but mostly warm. One power user, who runs eleven projects at once, is unhappy and vocal about it: the new flow assumes one project at a time.
Is 62% good?
You do not know, and — this is the part that matters — you cannot find out from this data. With 40 users, a result of 62% fits a true rate anywhere from about 47% to 76%: no better than the old flow's "roughly half," or a lot better. The number cannot tell those apart. The dashboard is not giving you a weak signal. It is giving you a number that looks like a signal.
Which puts you somewhere specific and uncomfortable. This is not a case where more analysis helps, and it is not a case where the data is bad — the beta ran fine, the number is correctly computed. It is a case where the test as designed could not have answered the question, and you are finding that out six days before launch.
So the question is not "ship or delay." It is: what do you do when the information you needed was never going to arrive, and how do you avoid arriving here again?
Core concepts
Each idea is a short read, one picture and one quick check.
Idea 1 of 4
A test that cannot fail is not a test
Pull up the plan the beta came from. It probably reads like the one marked up below: six weeks, open to any account that opts in, "learn and iterate."
Every word of it is reasonable, and the whole thing is unfalsifiable: no result it could produce would count as failure. "We gathered insight" is true whatever happens, including if nothing happens.
A test is a check whose result could tell you to stop. If both results lead to the same action, you did not run a test; you built something with extra steps. The fix is a kill condition: the result that would make you stop, written into the plan before any data exists.
Picture it
Beta plan · new first-project flow
- Six weeks, open to any account that opts in. (circled)whoever volunteers
- Success: gather insight into how users experience the flow. (struck out)can't come back "no"
- We'll learn and iterate. (struck out)same action either way
- Compared with: (not written) (circled)no baseline
- We stop if: (not written) (circled)the missing line
No result could have said stop.
Check yourself
Each line is a success criterion from a plan. Could the result come back "no"?
Success: gather insight into how users experience the new flow.
If fewer than 20% of pilot accounts finish setup in week one, we revert.
We'll evaluate the results at the readout.
Expand if completion beats the old flow's 48% by 8 points, measured the same way.
Validate that users like the new flow.
Stop the rollout if more than 2% of accounts open a billing ticket in the first fortnight.
Go deeper
How to use it. Before running anything, write down what result would make you stop, in the document, before the data exists. "If fewer than 20% of the pilot group complete the flow, we stop" is a test. "We'll evaluate the results" is not. Then check three things about the threshold:
- Is there a baseline? A threshold with nothing to compare against gets reinterpreted after the fact. What is the current rate, measured the same way?
- Can the sample tell the outcomes apart? If the threshold is 20% and the sample cannot tell 15% from 25%, the threshold is decorative. And a sample of whoever volunteers answers a question about volunteers.
- Was the comparison written down first? Stating it afterwards is unfalsifiable by construction.
How to spot it. Success described in verbs about learning: learn, iterate, gather, understand, validate. Those are what a plan says when nobody wants to name a number.
One thing that has changed. "Just build it and see" is now cheap enough to be superficially rational, and for small bets it often is. What matters is whether the learning is cheap, not whether the building is. A week-long build that produces no interpretable signal is still a wasted week, and now you also own a codebase.
Idea 2 of 4
What would change my mind
A product lead writes a confident memo recommending launch. Ask what result would make her reverse it and the room goes quiet. Nobody has written that down.
There is a question that costs nothing to ask and is almost never in the document: what would I have to see to reverse this? Answer it in writing, before the data.
Committing in advance to a disconfirming observation is the only cheap defence against reading every result as support. And every result will be read as support, by competent, honest people, because that is how reading works once you already have a conclusion.
Check yourself
The launch memo recommends shipping the new flow to every account on the 14th. Which line, written before launch, makes it a call that could turn out wrong?
Go deeper
How to use it. Write the answer in the document, before the data. It does two things. It makes the recommendation falsifiable, and it tells your team what evidence to go and find, which is often worth more than the discipline itself.
How to spot the gap. A confident recommendation with no named disconfirming observation. That combination is the reliable signature of a conclusion that came before its analysis: not a lie, just an order of operations that got reversed somewhere and never got noticed.
One thing that has changed. A model will draft a confident, well-argued recommendation in seconds, and it will not say what would reverse it unless asked. Asking is now the cheapest step in the review, and the one most often skipped, because the draft already reads as finished.
Idea 3 of 4
Which risk are you shipping against
Six days out, the launch memo's risks table reads: documentation may slip, support briefed, traffic spike covered. Every row is about whether the launch happens. None is about whether it should.
Chapter one's four risks come back here under time pressure: value (will they choose it?), usability (can they use it?), feasibility (can we build it?) and business viability (does it work for us: support, legal, margin?).
A launch decision is a decision to stop testing some of them. That is legitimate, because you cannot test everything. But it should be chosen, not defaulted into.
Check yourself
The six-week beta from Start here. Does it tell you this, or is the launch assuming it?
People can get through the new flow end to end.
New accounts will finish setup more often than on the old flow.
The team could build the flow and run it at beta scale.
Support can handle the questions when every new account gets it.
Accounts that run many projects at once find it slower.
Go deeper
How to use it. Name which risks the beta actually addressed, and say the rest out loud. "This de-risked usability; value is untested and we are shipping on the assumption that the enterprise segment behaves like the beta group" is a sentence that lets a reader agree or disagree with something real.
How to spot it. A launch memo whose risks table lists only delivery risks, like the one above. Under a deadline, feasibility gets over-reported because it is the risk that resolves cleanly and produces confident sentences. Business viability gets under-reported because its costs (support load, brand, legal, margin) arrive after the launch and belong to other teams.
One thing that has changed. When shipping is cheap, more decisions become reversible, and reversibility should change how much evidence you demand. Demanding the same rigour for a reversible bet as for an irreversible one is its own error. What does not become reversible: the promise made to customers, the support surface created, and what your positioning now claims.
Idea 4 of 4
What "ship a subset" actually buys
Someone in the launch meeting says "let's just turn it on for 20% and see." The room relaxes. Shipping to some accounts but not all is the middle option in almost every launch call, and it is usually right, for a reason nobody states.
Shipping to a subset buys you a second sample, under real conditions, at a size you choose. But only if you decide in advance what that sample is supposed to answer, and what you will do with each answer.
A subset with no threshold and no decision date is not a cautious launch. It is a full launch with a smaller denominator and a delay attached. It feels responsible, which is why it is the most common way this decision gets made badly.
Check yourself
Marketing suggests a soft launch: "turn it on for 20% of accounts and see how it goes." What makes that subset worth having?
Go deeper
How to use it. If you ship a subset, write three things: which segment and why that one, what number decides, and the date the decision gets made. Without the third, the subset becomes permanent by drift. Pick the segment by a rule anyone could apply, not by who was easiest to switch on, or the second sample inherits the first one's bias.
Picture it
A subset that decides
- Segment chosen by a written rule
- One number decides expand or roll back
- A decision date and a named owner
A subset that drifts
- Whoever was easiest to switch on
- "We'll expand when we're confident"
- No date, so nobody has to decide
How to spot it. A rollout plan that says "expand when we're confident." Ask what number would make them confident, and by when. If nobody knows, the subset has no question attached.
Back to the 62%. The beta established that the flow works mechanically and that some people are fine with it. It did not establish the completion rate, because it could not. That leaves three defensible calls, and they really are defensible. Ship, with the untested risk named. Delay, if the cost of being wrong is high enough to buy a real sample. Ship to a subset, with a threshold and a date. What is not defensible is treating 62% as though it meant something. The failure is not the choice. It is the plan, six weeks ago, that produced a number nobody could act on.
One thing that has changed. Feature flags make a subset launch nearly free to set up, so more launches start as one. The setup got cheap; deciding did not. The flag is still on, at 20%, long after anyone remembers what it was meant to answer.
Worked examples
Make the call yourself first. The reasoning opens after you choose.
Example 1 of 3
The threshold that arrived too late
A team runs a two-week experiment on a new pricing page. Conversion is 3.4% against 3.1% for the old page. The review has argued for half an hour about whether that gap means anything. The analyst's quick check says a gap this size is well inside the noise at their traffic, and both sides are now arguing about interpretation with nothing to appeal to. Someone asks what the plan said the threshold was. There was no plan; the experiment was set up in an afternoon.
Check yourself
What is the most useful thing the team can do now?
Example 2 of 3
The pilot that could only succeed
A hiring-software company plans a six-week pilot of a new interview-scheduling assistant with 300 recruiters. It is described as "learn and iterate," and success is defined as "gathering insight into how recruiters use it." Engineering, Sales and Support have all approved it. A reviewer reads it before kickoff and plans a short redline: a baseline, a kill threshold, a check that 300 recruiters can show the difference, and a named decider with a date.
Check yourself
Which fix has to come first, because the others depend on it?
Example 3 of 3
The launch that was right to ship and wrong to claim
A company ships a feature to all customers after a beta with 30 accounts that opted in. It is plausibly the right call: the feature is additive and easy to reverse, and the beta surfaced no serious problems. The launch memo is nearly done. Its last line reads: "The beta validated strong demand."
Check yourself
What should that line say instead?
Case studies
Real situations with more than one defensible reading.
Case 1 of 1
The beta whose data cannot distinguish the outcomes
An invented composite, built from the pattern rather than any real company.
A project-management product for construction firms has rebuilt the flow where a site manager creates their first project, the point where new accounts have always stalled. Six-week beta: 40 accounts, opted in. 62% completed the new flow within a week of signup. The baseline for the old flow is "roughly half," from an old report whose query nobody can find, so nobody knows how it was defined. New signups run at about 90 a month.
General availability is in six days. Marketing is briefed, a partner announcement is coordinated, and two engineers have holidays booked on the assumption it ships. Feedback is mostly positive. One power user, who runs eleven projects at once, is loudly unhappy: the new flow assumes a single project, so his setup is slower.
Check yourself
You owe a recommendation by Thursday. What should it lead with?
What great operators do
The rules this chapter's scenarios test for, and how to tell when someone follows them.
Rules to keep
Before you open each card, say what you'd look for.
Common failure patterns
How smart people get this wrong. Find each one in the wild.
Trap 1 of 2
Unfalsifiable pilot
What it looks like. A test with no stated failure condition, or thresholds set after the results arrive. Often paired with a sample too small to tell any outcome from noise, and a plan to "learn and iterate" regardless.
Check yourself
Tap the lines that mean this test can't come back "no".
Experiment plan — 14-day vs 30-day free trial
Found 0 of 2.
Why smart people do it. Pre-committing to a kill threshold means sometimes having to kill your own project in public. Leaving it open preserves the option to be right, and nobody in the approval meeting has an incentive to close it.
The correction. Write the kill condition before the test and put it in the document. If nobody will agree to a threshold, the organisation is not running a test; it is building with extra steps.
Trap 2 of 2
Fluency mistaken for rigour
What it looks like. A well-structured, confidently worded launch memo, with the right headings, a risks table and a phased plan, in which no claim is sourced and no number is traceable. It reads like the good version of this document.
Check yourself
Tap the claims the memo rests on that can't be traced to anything.
Launch memo — new first-project flow, general availability
Found 0 of 2.
Why smart people do it. Format was a real signal for decades. Producing a polished strategy document used to require the thinking that justified it. That link broke; the reading habit didn't.
The correction. Read for traceability rather than structure. Pick the three load-bearing claims and ask where each came from. Treat "it reads well" as carrying no information about whether the analysis happened.
Cheat sheet
The whole chapter on one card. Save it or share it.
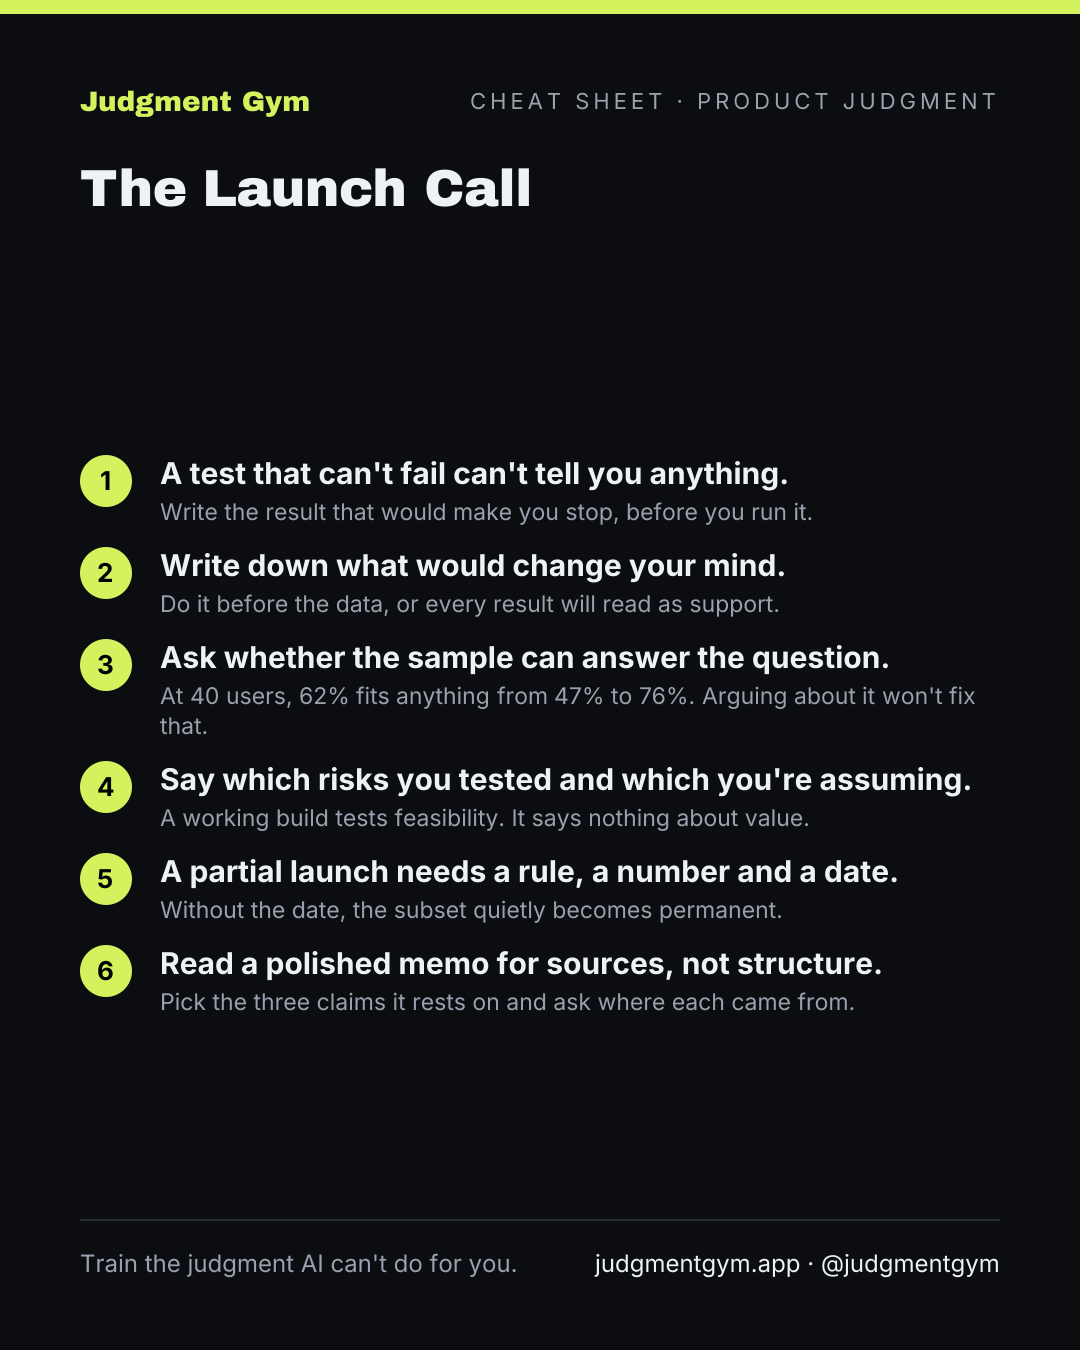
The Launch Call
- 1A test that can't fail can't tell you anything.Write the result that would make you stop, before you run it.
- 2Write down what would change your mind.Do it before the data, or every result will read as support.
- 3Ask whether the sample can answer the question.At 40 users, 62% fits anything from 47% to 76%. Arguing about it won't fix that.
- 4Say which risks you tested and which you're assuming.A working build tests feasibility. It says nothing about value.
- 5A partial launch needs a rule, a number and a date.Without the date, the subset quietly becomes permanent.
- 6Read a polished memo for sources, not structure.Pick the three claims it rests on and ask where each came from.
Memes
The failure patterns, one picture each. For the group chat.
Your turn
Make the call
The first two checkpoints test opposite ends of the chapter: the decision under pressure, and the plan that created the pressure. In the first you get the beta from Start here, six days before launch: you say what the numbers can support, then choose ship, delay or a split. In the second you get an approved pilot plan the Friday before kickoff and decide what to send back so that it could return a "no". Do them in that order: making the call badly is what makes the redline feel urgent. The third, a rollout that has sat at 20% for eleven weeks, is a quick rep on what a subset launch needs.
The trap. Arguing about whether 62% is good. The sample can't answer that, and the baseline it is compared with doesn't survive one look. In the pilot, the trap is adding a threshold and stopping there: without a baseline measured the same way, the threshold gets reinterpreted at the readout.
Ship it on forty users?: Make the call for Marisol
Say what the beta can support, then choose ship, delay or split
The pilot with no way to fail: Send it back, or approve?
Read one part of the plan closely, then decide what Marcus gets back before Monday